简介 7 G2 {. z: {8 b# I ) @/ ^/ B7 A n2 }9 E) j% t8 a 下载安装 0 Y% t8 J/ z( i) X. f9 m1 e https://github.com/alirezamika/autoscraper - D% [ e; U1 X: j. `& Y 兼容 Python 3。可使用以下方法进行安装:& K: A" t9 R6 J (1)从git获取安装 $ pip install git+https://github.com/alirezamika/autoscraper.git 7 t( Z3 ]( k1 O" q0 d) t+ N , e1 [- [, g3 p \/ {7 O! C (3)下载源码后进行安装 $ python setup.py install( K+ j' f" h/ W; n6 H$ @! \) P 简单使用 ) A+ [ s0 ~7 @! s% ] Z6 ~ d- {1 x7 _3 ]7 @ from autoscraper import AutoScraper
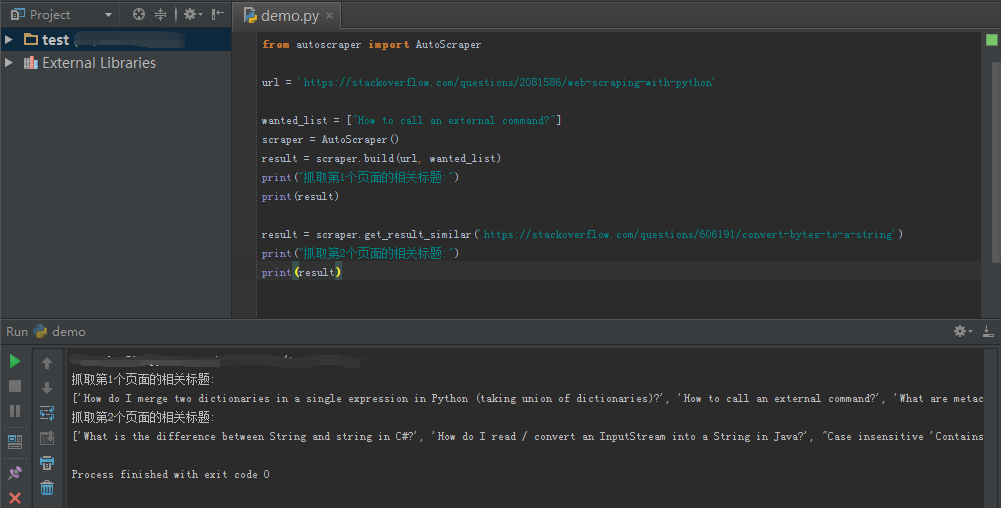
url = 'https://stackoverflow.com/questions/2081586/web-scraping-with-python'
wanted_list = ["How to call an external command?"]
scraper = AutoScraper()
result = scraper.build(url, wanted_list)
print(result)8 r1 O6 H9 G( {+ L [
'How do I merge two dictionaries in a single expression in Python (taking union of dictionaries)?',
'How to call an external command?',
'What are metaclasses in Python?',
'Does Python have a ternary conditional operator?',
'How do you remove duplicates from a list whilst preserving order?',
'Convert bytes to a string',
'How to get line count of a large file cheaply in Python?',
"Does Python have a string 'contains' substring method?",
'Why is “1000000000000000 in range(1000000000000001)” so fast in Python 3?'
]抓取相似结果 . {( b' b1 G- b. o 当你还想获取stackoverflow上其他页面中所有相关的文章标题,则可以直接通过get_result_similar方法获取:5 n0 C% k: O. I scraper.get_result_similar('https://stackoverflow.com/questions/606191/convert-bytes-to-a-string')7 O7 R; e2 ]1 }
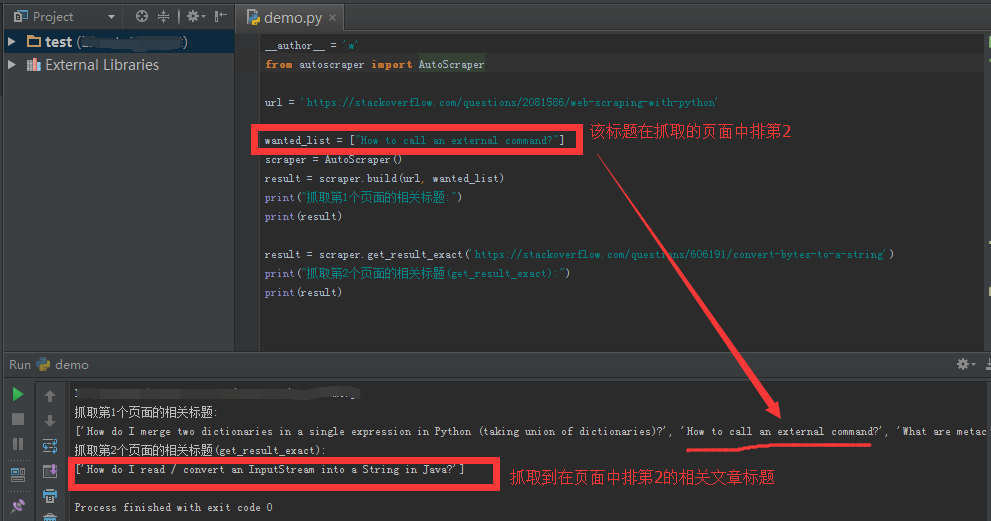
B# _8 v$ h% X0 _; {' k5 U$ _: } 抓取确切结果 ; t" q5 j1 C7 E 当你只想抓取某个确切的结果,可以使用get_result_exact方法,即从wanted_list中以完全相同的顺序检索数据:6 ?0 `3 n0 Y8 \( k6 _) V scraper.get_result_exact('https://stackoverflow.com/questions/606191/convert-bytes-to-a-string')' @* [- X" `& ?2 Y* F5 q) D
2 N1 p# |/ E+ {; q9 c* }/ @ 自定义请求模块参数 ' u3 O1 h0 T/ Q @# p2 u 你还可以传递任何自定义请求模块参数。例如,你可能想使用代理或自定义头:7 T% t r; s! o3 e proxies = {
"http": 'http://127.0.0.1:8001',
"https": 'https://127.0.0.1:8001',
}
result = scraper.build(url, wanted_list, request_args=dict(proxies=proxies))抓取多项信息 ) ^# t4 K3 _/ |* J 假设我们想要抓取关于文本,Star的数量和Github回购页面的问题链接:+ k8 H- p5 w" C `5 x4 S from autoscraper import AutoScraper
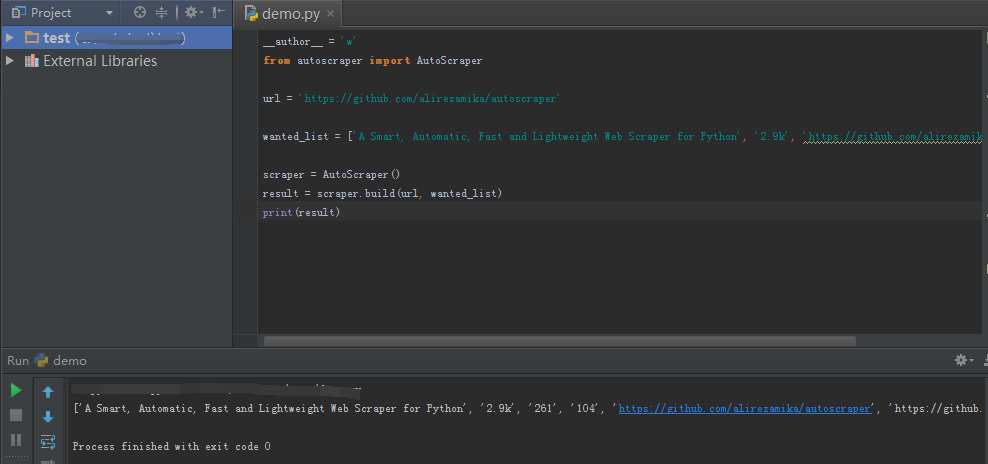
url = 'https://github.com/alirezamika/autoscraper'
wanted_list = ['A Smart, Automatic, Fast and Lightweight Web Scraper for Python', '2.5k', 'https://github.com/alirezamika/autoscraper/issues']
scraper = AutoScraper()
scraper.build(url, wanted_list)% X( N3 G7 m8 c8 M
+ J/ n4 D) F+ ?2 Q. r 保存模型 / t2 D' k4 z; _* j' x( E* o% g& j 我们可以保存抓取的模型以便以后使用:. Q& K7 ~! i6 I( z # 指定保存的文件路径
scraper.save('stackoverflow')
# 调用方法:
scraper.load('stackoverflow'): }: S% V! V- e 4 V0 i. X# o! ]) c. p# f  |手机版|小黑屋|paopaomj.COM
(
 渝ICP备18007172号|
 渝公网安备50010502503914号 )


 发表于 2021-1-11 13:34:43